Open Source · ActivoEnglish Brain — Tu coach de entrevistas en inglés con IA, autoalojado
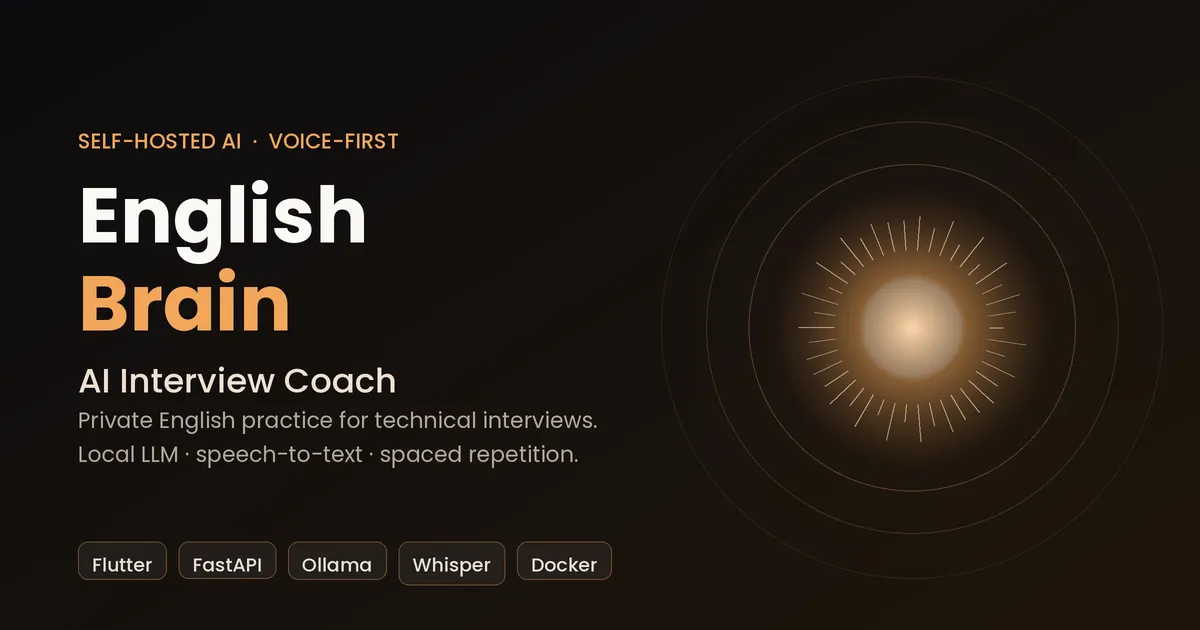
Una plataforma privada y autoalojada para preparar entrevistas técnicas en inglés hablando, no escribiendo. Tocas un orbe, hablas, y el coach te transcribe, te corrige la pronunciación fonema a fonema y te programa el repaso con repetición espaciada (py-fsrs). Toda la IA —el modelo de lenguaje, el reconocimiento de voz y la síntesis— corre en tu propio hardware: tu voz y tus respuestas nunca salen de tu red. Por dentro: cliente Flutter (Android, Web y Windows), orquestador FastAPI y una arquitectura GPU híbrida sobre Docker + Caddy.
IA localVozFlutterFastAPISelf-hostedPronunciación
English Brain te prepara para entrevistas técnicas en inglés hablando, no
escribiendo. En vez de un chatbot genérico, la pantalla principal es un único
orbe de voz: lo tocas, hablas, y el coach te devuelve la respuesta en
streaming palabra a palabra mientras la pronuncia — pensado para pulir la
pronunciación y la fluidez como lo exige una entrevista real.
Qué hace
- Coaching por voz: una conversación hablada en vivo con un coach de IA —
respuestas en streaming (SSE), síntesis de voz natural y feedback estructurado
sobre tus respuestas.
- Motor de pronunciación: puntuación a nivel de palabra y de fonema con
wav2vec2, alineamiento forzado (MFA) y curvas de entonación nativas
precalculadas por frase.
- Repetición espaciada: cada ítem que practicas se programa con el algoritmo
oficial
py-fsrs, así repasas justo cuando estás a punto de olvidar.
- Curso completo: preguntas de entrevista, reading y listening (etiquetados
CEFR), vocabulario y gramática — todo hablable y cacheado.
- Offline-first: contenido cache-first con seeds embebidos; las lecciones y el
audio cargan aunque no haya backend.
- Actualizaciones OTA: parches de Dart y assets al móvil por internet con
Shorebird, sin reinstalar.
Privado por construcción
El modelo de lenguaje (Ollama), el reconocimiento de voz (Whisper) y la síntesis
(Kokoro) corren en hardware que tú controlas. No hay cuenta en la nube, ni API de
terceros, ni telemetría — tu voz, tus respuestas y tu progreso nunca salen de tu
red.
Por dentro
- Cliente (Flutter · Dart 3): Android, Web y Windows desde un solo código —
Riverpod, Drift (SQLite), go_router, Material 3 e i18n español/inglés.
- Backend (FastAPI · Python): el orquestador único — auth JWT, planificación
FSRS, un router de proveedores con degradación elegante, streaming SSE y caché
de audio/entonación en servidor.
- Arquitectura GPU híbrida: un NAS siempre encendido (Synology · Docker) para
auth, planificación y caché; una máquina GPU opcional para la inferencia pesada
(Ollama, Speaches, wav2vec2, MFA). El STT cae a CPU en el NAS si hace falta.
- Edge: Caddy para TLS automático, cabeceras de seguridad y streaming SSE;
WireGuard opcional para acceso remoto.
English Brain trains you for technical interviews in English by speaking, not typing. Instead of a generic chatbot, the home screen is a single calm voice orb: you tap, talk, and the coach streams its reply back token by token while it speaks — built to sharpen pronunciation and fluency the way a real interview demands.
What it does
- Voice-first coaching: a live spoken conversation with an AI coach — streaming replies over SSE, natural TTS playback, and structured feedback on your answers.
- Pronunciation engine: word- and phoneme-level scoring with wav2vec2, forced alignment (MFA) and native intonation curves precomputed per phrase.
- Spaced repetition: every item you practice is scheduled with the official
py-fsrs algorithm, so you review exactly when you're about to forget.
- Full course: interview questions, reading & listening (CEFR-tagged), vocabulary and grammar — all speakable, all cached.
- Offline-first: cache-first content with bundled seeds; lessons and audio still load with no backend reachable.
- OTA updates: Dart + asset patches shipped to installed phones over the air with Shorebird, no reinstall.
Private by construction
The language model (Ollama), speech-to-text (Whisper) and text-to-speech (Kokoro) all run on hardware you control. There's no cloud account, no third-party API and no telemetry — your voice, answers and progress never leave your network.
Under the hood
- Client (Flutter · Dart 3): Android, Web and Windows from one codebase — Riverpod, Drift (SQLite), go_router, Material 3, ES/EN i18n.
- Backend (FastAPI · Python): the single orchestrator — JWT auth, FSRS scheduling, a provider router with graceful degradation, SSE streaming and server-side audio/pitch caching.
- Hybrid GPU architecture: an always-on NAS (Synology · Docker) handles auth, scheduling and cache; an optional GPU box runs the heavy inference (Ollama, Speaches, wav2vec2, MFA). STT falls back to CPU on the NAS.
- Edge: Caddy for automatic TLS, security headers and SSE streaming; optional WireGuard for remote access.